
TL;DR

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
A comprehensive local document processing pipeline has been developed, enabling organizations to run all AI tasks on their own infrastructure. This architecture emphasizes simplicity, reliability, and data provenance, addressing key operational needs.
This week, a detailed architecture for a complete, end-to-end local document processing pipeline for AI was revealed, emphasizing operational simplicity, data governance, and model flexibility. This development offers organizations a blueprint for running all stages of document ingestion, OCR, extraction, and storage on their own infrastructure, without reliance on external services.
The architecture, described by Thorsten Meyer, consolidates key principles such as treating models as appliances, maintaining narrow CLI interfaces, and using PostgreSQL as the central queue and storage system. It ensures that each stage — from ingestion to structured extraction — is modular, version-controlled, and robust against failures. The pipeline supports content hashing for idempotency, enabling safe retries and reprocessing without duplication.
Key components include a simple watch folder or upload endpoint for ingestion, a dedicated OCR CLI, a PostgreSQL-backed job queue with features like SKIP LOCKED for concurrency, and a separate extraction pass that converts markdown to structured JSON. Provenance data is stored alongside extracted information, allowing full traceability for audits or future analysis. The architecture is designed to adapt quickly to model swaps and updates, with minimal disruption.
Why a Fully Local Document Pipeline Matters for AI Deployment
This architecture addresses critical operational challenges faced by organizations deploying AI for document processing. It reduces reliance on external cloud services, enhances data privacy and security, and simplifies compliance with regulations. By maintaining a versioned, transparent pipeline, organizations can ensure reproducibility, auditability, and easier debugging. The design also enables faster iteration on models and workflows, making AI deployment more sustainable and scalable in regulated or sensitive environments.
Products Worth Considering
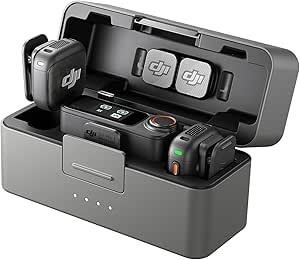
DJI Mic 3 Wireless Microphone System (2 Transmitters, 1 Receiver, Charging Case)

EcoFlow Smart Home Panel 2 Whole-Home Backup System Hub

LG UltraGear 32GX850A-B 32-Inch 4K UHD Glossy OLED Gaming Monitor
As an affiliate, we earn on qualifying purchases.
Background and Development of Local Document Pipelines
Recent developments in AI models, such as open-source OCR and large language models, have increased the feasibility of fully local processing. Previously, many organizations relied on cloud services for OCR and extraction, which posed data governance and operational risks. The industry has responded with architectures emphasizing modularity, version control, and robustness. Thorsten Meyer’s recent outline synthesizes these trends into a concrete reference architecture, addressing operational needs like concurrency, retries, and provenance tracking, which are often overlooked in simpler pipelines.
“This pipeline is designed to be simple to operate, modular, and version-controlled, enabling organizations to run everything locally without sacrificing reliability or traceability.”
— Thorsten Meyer
Unanswered Questions About Adoption and Implementation Challenges
While the architecture is well-defined, it remains unclear how readily organizations will adopt this approach at scale. Specific challenges include integrating existing workflows, training staff on new tooling, and managing model updates without disrupting operations. Additionally, the performance of local models versus cloud-based solutions in diverse real-world scenarios is still under evaluation. The long-term maintenance and evolution of such pipelines also present open questions.
Next Steps for Deployment and Community Adoption
Organizations and developers are expected to start implementing this architecture in pilot projects, testing its robustness and flexibility. Further refinement and tooling support will likely emerge, easing integration. Industry groups may also develop best practices around model versioning, provenance, and operational monitoring. As adoption grows, shared repositories and open standards could facilitate wider deployment and interoperability.
Key Questions
What are the main benefits of this local document pipeline?
The pipeline offers improved data privacy, regulatory compliance, operational reliability, and ease of model updates, all while maintaining full control over the processing environment.
Can existing workflows be integrated into this architecture?
Integration depends on the current setup, but the modular design aims to make it adaptable. Organizations may need to develop custom connectors or adjust stages for compatibility.
How does this architecture handle model updates?
Model swaps are designed to be seamless, with version-controlled prompts and configurations, minimizing disruption and enabling rapid iteration.
Is this approach suitable for regulated industries?
Yes, the architecture emphasizes provenance, auditability, and data governance, making it well-suited for sectors with strict compliance requirements.
What are the technical requirements to implement this pipeline?
Organizations need a PostgreSQL database, local compute resources for OCR and extraction models, and basic scripting capabilities for orchestration. No specialized broker or external cloud services are required.
Source: ThorstenMeyerAI.com